Quran Lab

SAWT V5 listening samples

SAWT V5 is the second public SAWT model. All versions of each clip are matched for loudness, and headphones are recommended.

Google's Miipher-2 demo clips

English, noisy read speech

8.1 s

Quality predictor 2.83 to 4.58 (Miipher-2 4.52). Bandwidth 12 to 21 kHz (Miipher-2 renders are 24 kHz audio). Speaker similarity 0.982.

Damaged input
DistillMOS 2.83PQ 4.3812 kHz
SAWT V5
DistillMOS 4.58PQ 7.1621 kHzspeaker 0.982
SAWT V4
DistillMOS 4.38PQ 7.4021 kHzspeaker 0.984
Miipher-2 (Google)
DistillMOS 4.52PQ 7.3712 kHzspeaker 0.982

Swahili, FLEURS recording

18.7 s

Quality predictor 3.16 to 4.48 (Miipher-2 4.29). Bandwidth 8 to 23 kHz (Miipher-2 renders are 24 kHz audio). Speaker similarity 0.984.

Damaged input
DistillMOS 3.16PQ 4.328 kHz
SAWT V5
DistillMOS 4.48PQ 5.7423 kHzspeaker 0.984
SAWT V4
DistillMOS 4.16PQ 6.2323 kHzspeaker 0.976
Miipher-2 (Google)
DistillMOS 4.29PQ 5.5712 kHzspeaker 0.987

Urdu, FLEURS recording

12.5 s

Quality predictor 2.69 to 4.53 (Miipher-2 4.42). Bandwidth 8 to 21 kHz (Miipher-2 renders are 24 kHz audio). Speaker similarity 0.981.

Damaged input
DistillMOS 2.69PQ 4.908 kHz
SAWT V5
DistillMOS 4.53PQ 7.3521 kHzspeaker 0.981
SAWT V4
DistillMOS 3.93PQ 6.7623 kHzspeaker 0.986
Miipher-2 (Google)
DistillMOS 4.42PQ 7.2912 kHzspeaker 0.979

Catalan, FLEURS recording

9.5 s

Quality predictor 3.12 to 4.65 (Miipher-2 4.70). Bandwidth 8 to 23 kHz (Miipher-2 renders are 24 kHz audio). Speaker similarity 0.958.

Damaged input
DistillMOS 3.12PQ 5.008 kHz
SAWT V5
DistillMOS 4.65PQ 7.6623 kHzspeaker 0.958
SAWT V4
DistillMOS 4.49PQ 7.5823 kHzspeaker 0.968
Miipher-2 (Google)
DistillMOS 4.70PQ 7.7312 kHzspeaker 0.961

English, the clip SAWT V4 lost

5.6 s

Quality predictor 3.57 to 4.44 (Miipher-2 4.60). Bandwidth 12 to 21 kHz (Miipher-2 renders are 24 kHz audio). Speaker similarity 0.988.

Damaged input
DistillMOS 3.57PQ 5.8712 kHz
SAWT V5
DistillMOS 4.44PQ 7.3221 kHzspeaker 0.988
SAWT V4
DistillMOS 1.59PQ 6.5423 kHzspeaker 0.595
Miipher-2 (Google)
DistillMOS 4.60PQ 7.4612 kHzspeaker 0.962

LibriTTS-R, against Google's Miipher renders

English audiobook (LibriTTS)

6.3 s

Quality predictor 3.75 to 4.65 (Miipher 4.49). Bandwidth 12 to 20 kHz (Miipher renders are 24 kHz audio). Speaker similarity 0.979.

Damaged input
DistillMOS 3.75PQ 5.8912 kHz
SAWT V5
DistillMOS 4.65PQ 7.5620 kHzspeaker 0.979
SAWT V4
DistillMOS 4.47PQ 7.3220 kHzspeaker 0.977
Miipher (Google, LibriTTS-R)
DistillMOS 4.49PQ 7.6712 kHzspeaker 0.980

English audiobook (LibriTTS)

8.9 s

Quality predictor 4.01 to 4.48 (Miipher 4.20). Bandwidth 12 to 22 kHz (Miipher renders are 24 kHz audio). Speaker similarity 0.995.

Damaged input
DistillMOS 4.01PQ 5.6412 kHz
SAWT V5
DistillMOS 4.48PQ 6.6722 kHzspeaker 0.995
SAWT V4
DistillMOS 4.16PQ 6.4723 kHzspeaker 0.997
Miipher (Google, LibriTTS-R)
DistillMOS 4.20PQ 6.4912 kHzspeaker 0.985

Quran recitation from the archive

Quran recitation, archive upload (surah 85)

10.0 s

Quality predictor 2.53 to 3.80 (SAWT V4 3.91). Bandwidth 8 to 16 kHz. Speaker similarity 0.936.

Damaged input
DistillMOS 2.53PQ 5.968 kHz
SAWT V5
DistillMOS 3.80PQ 7.7316 kHzspeaker 0.936
SAWT V4
DistillMOS 3.91PQ 7.6416 kHzspeaker 0.937

Quran recitation, archive upload (surah 38)

10.0 s

Quality predictor 2.88 to 4.05 (SAWT V4 3.79). Bandwidth 11 to 16 kHz. Speaker similarity 0.978.

Damaged input
DistillMOS 2.88PQ 6.8111 kHz
SAWT V5
DistillMOS 4.05PQ 7.2916 kHzspeaker 0.978
SAWT V4
DistillMOS 3.79PQ 7.3514 kHzspeaker 0.981

The telephone clip from the SAWT V4 card

Danish over a telephone line

12.0 s

Quality predictor 3.06 to 4.68 (SAWT V4 4.60). Bandwidth 3.7 to 22 kHz (input: 300 to 3700 Hz telephone line). Speaker similarity 0.982.

Damaged input
DistillMOS 3.06PQ 4.073.7 kHz
SAWT V5
DistillMOS 4.68PQ 6.4822 kHzspeaker 0.982
SAWT V4
DistillMOS 4.60PQ 6.9621 kHzspeaker 0.982

Spectrograms

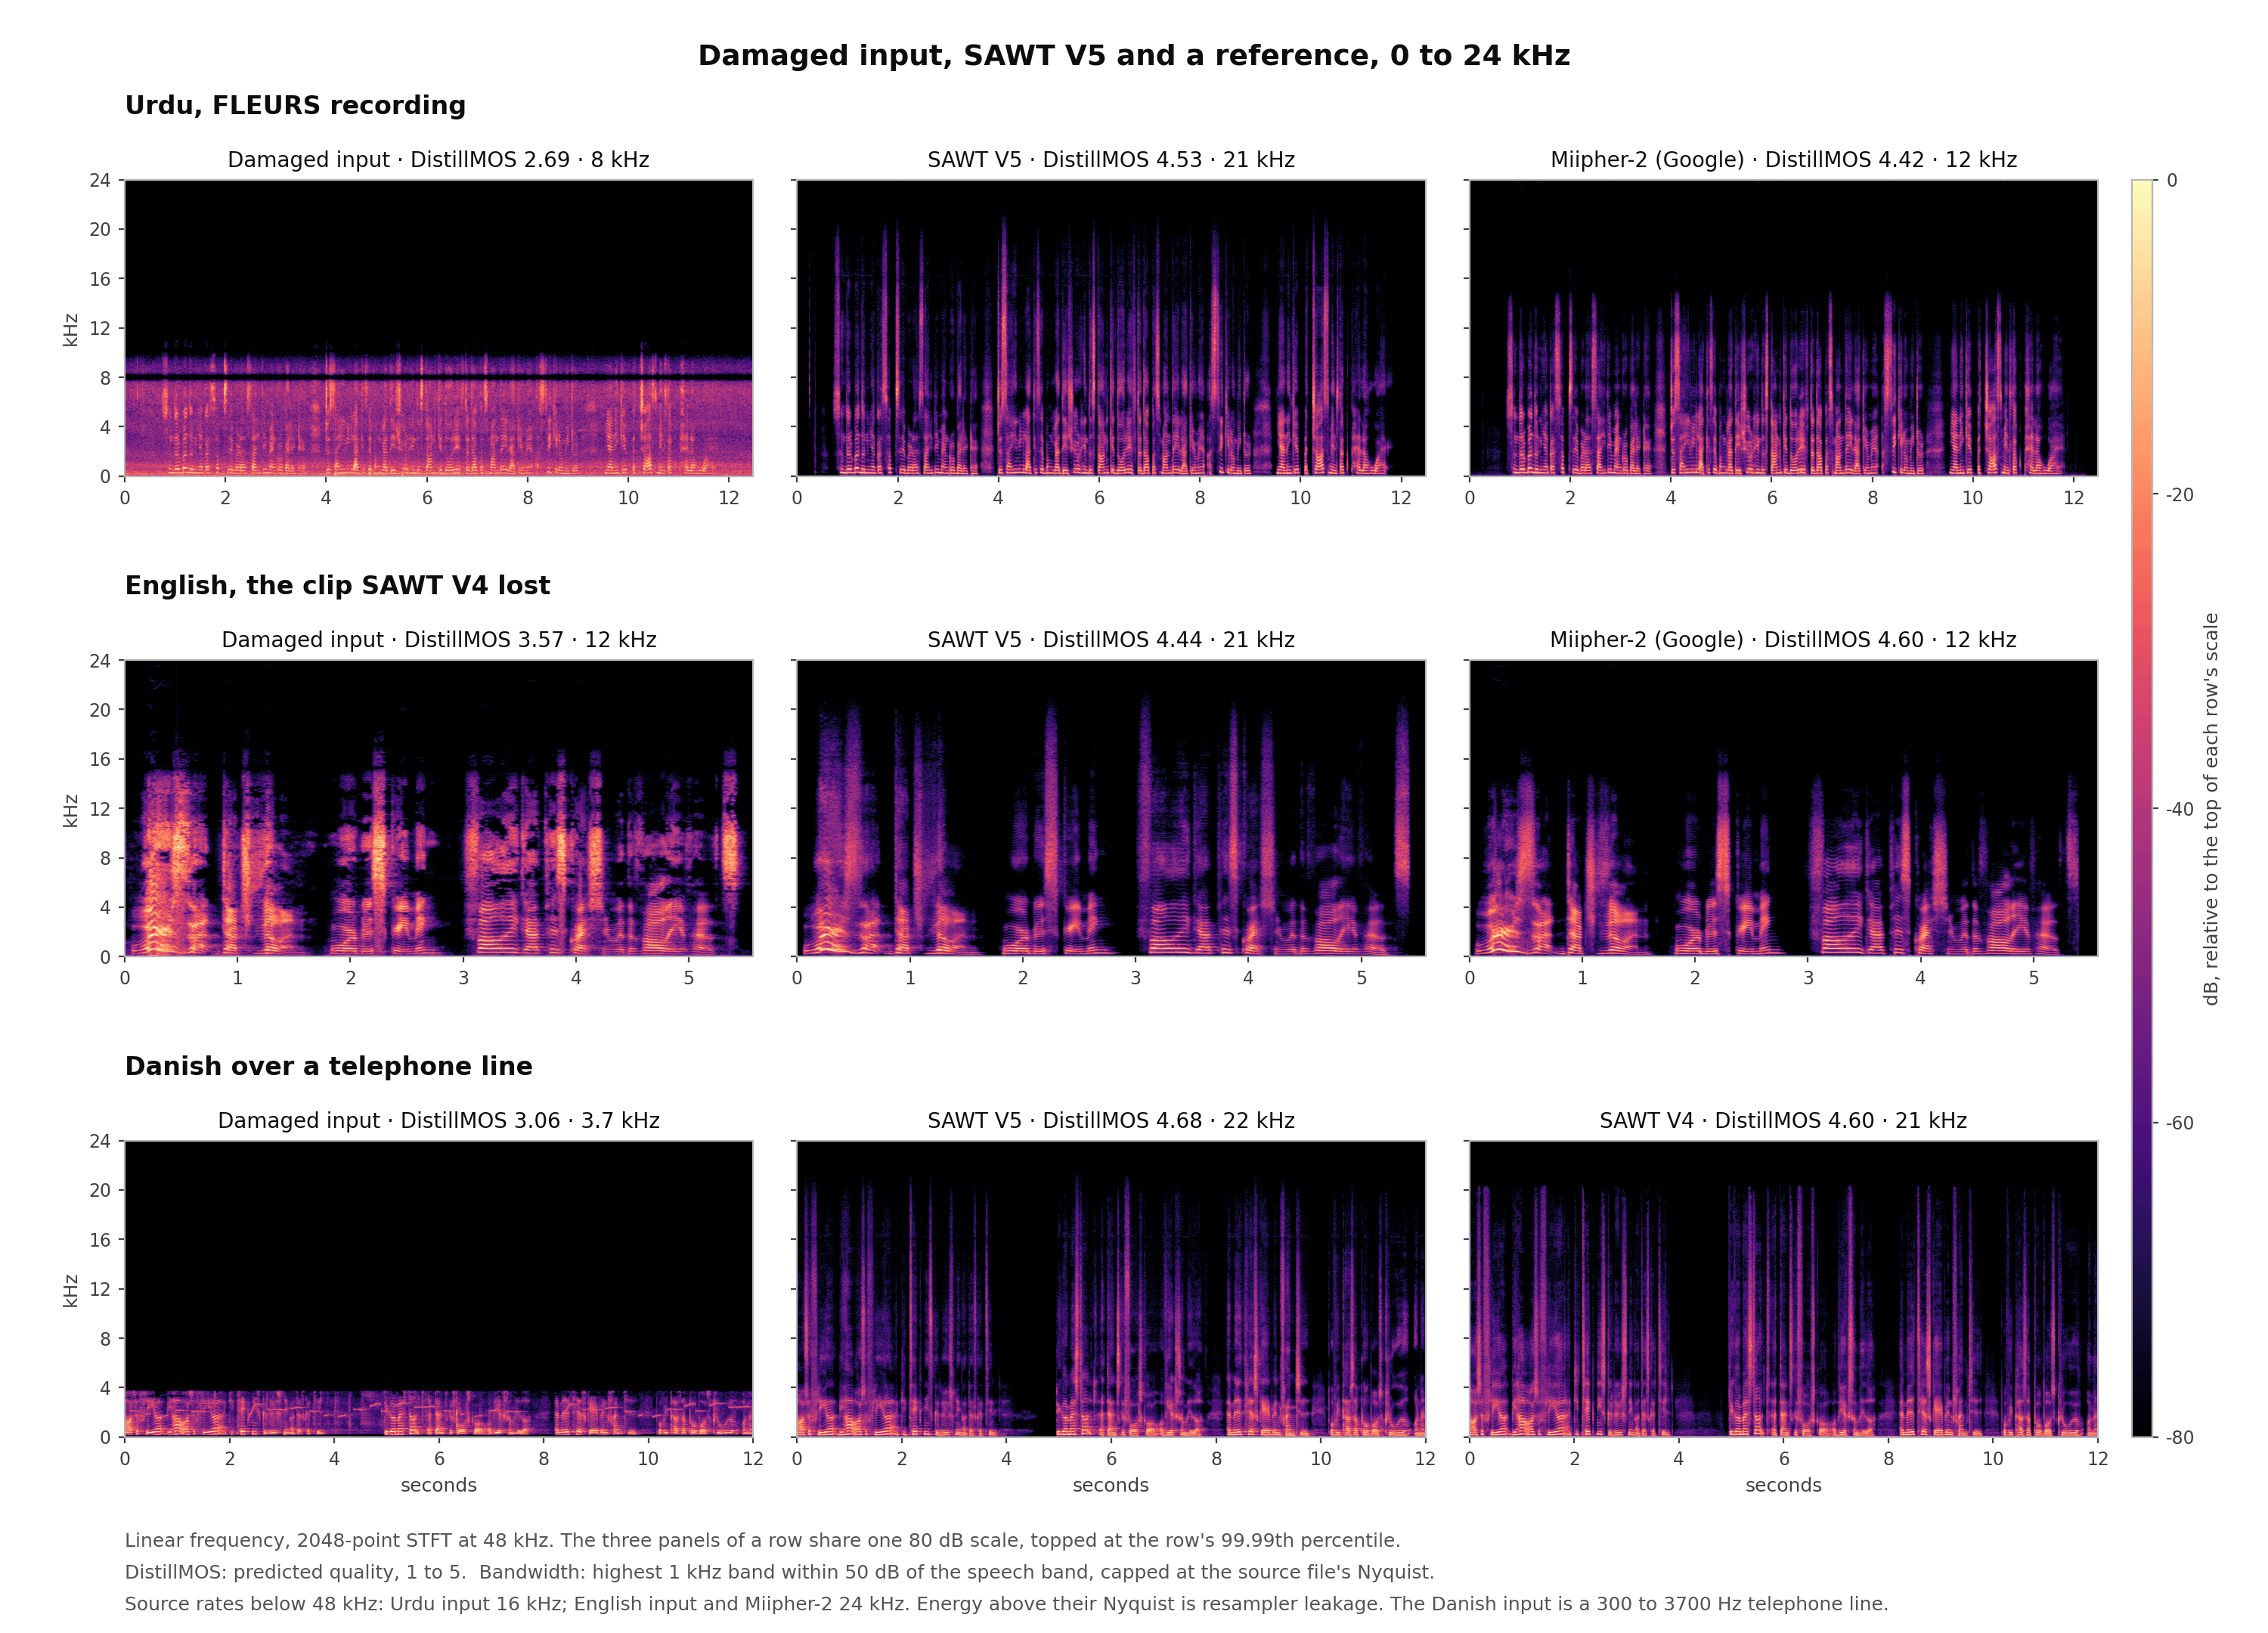
Spectrograms, 0 to 24 kHz, of three clips from this page: the damaged input, SAWT V5, and Miipher-2 or SAWT V4.
Three of the clips above: the damaged input, SAWT V5, and Miipher-2 (Urdu, English) or SAWT V4 (Danish). Open the image for full size.

Inference pipeline

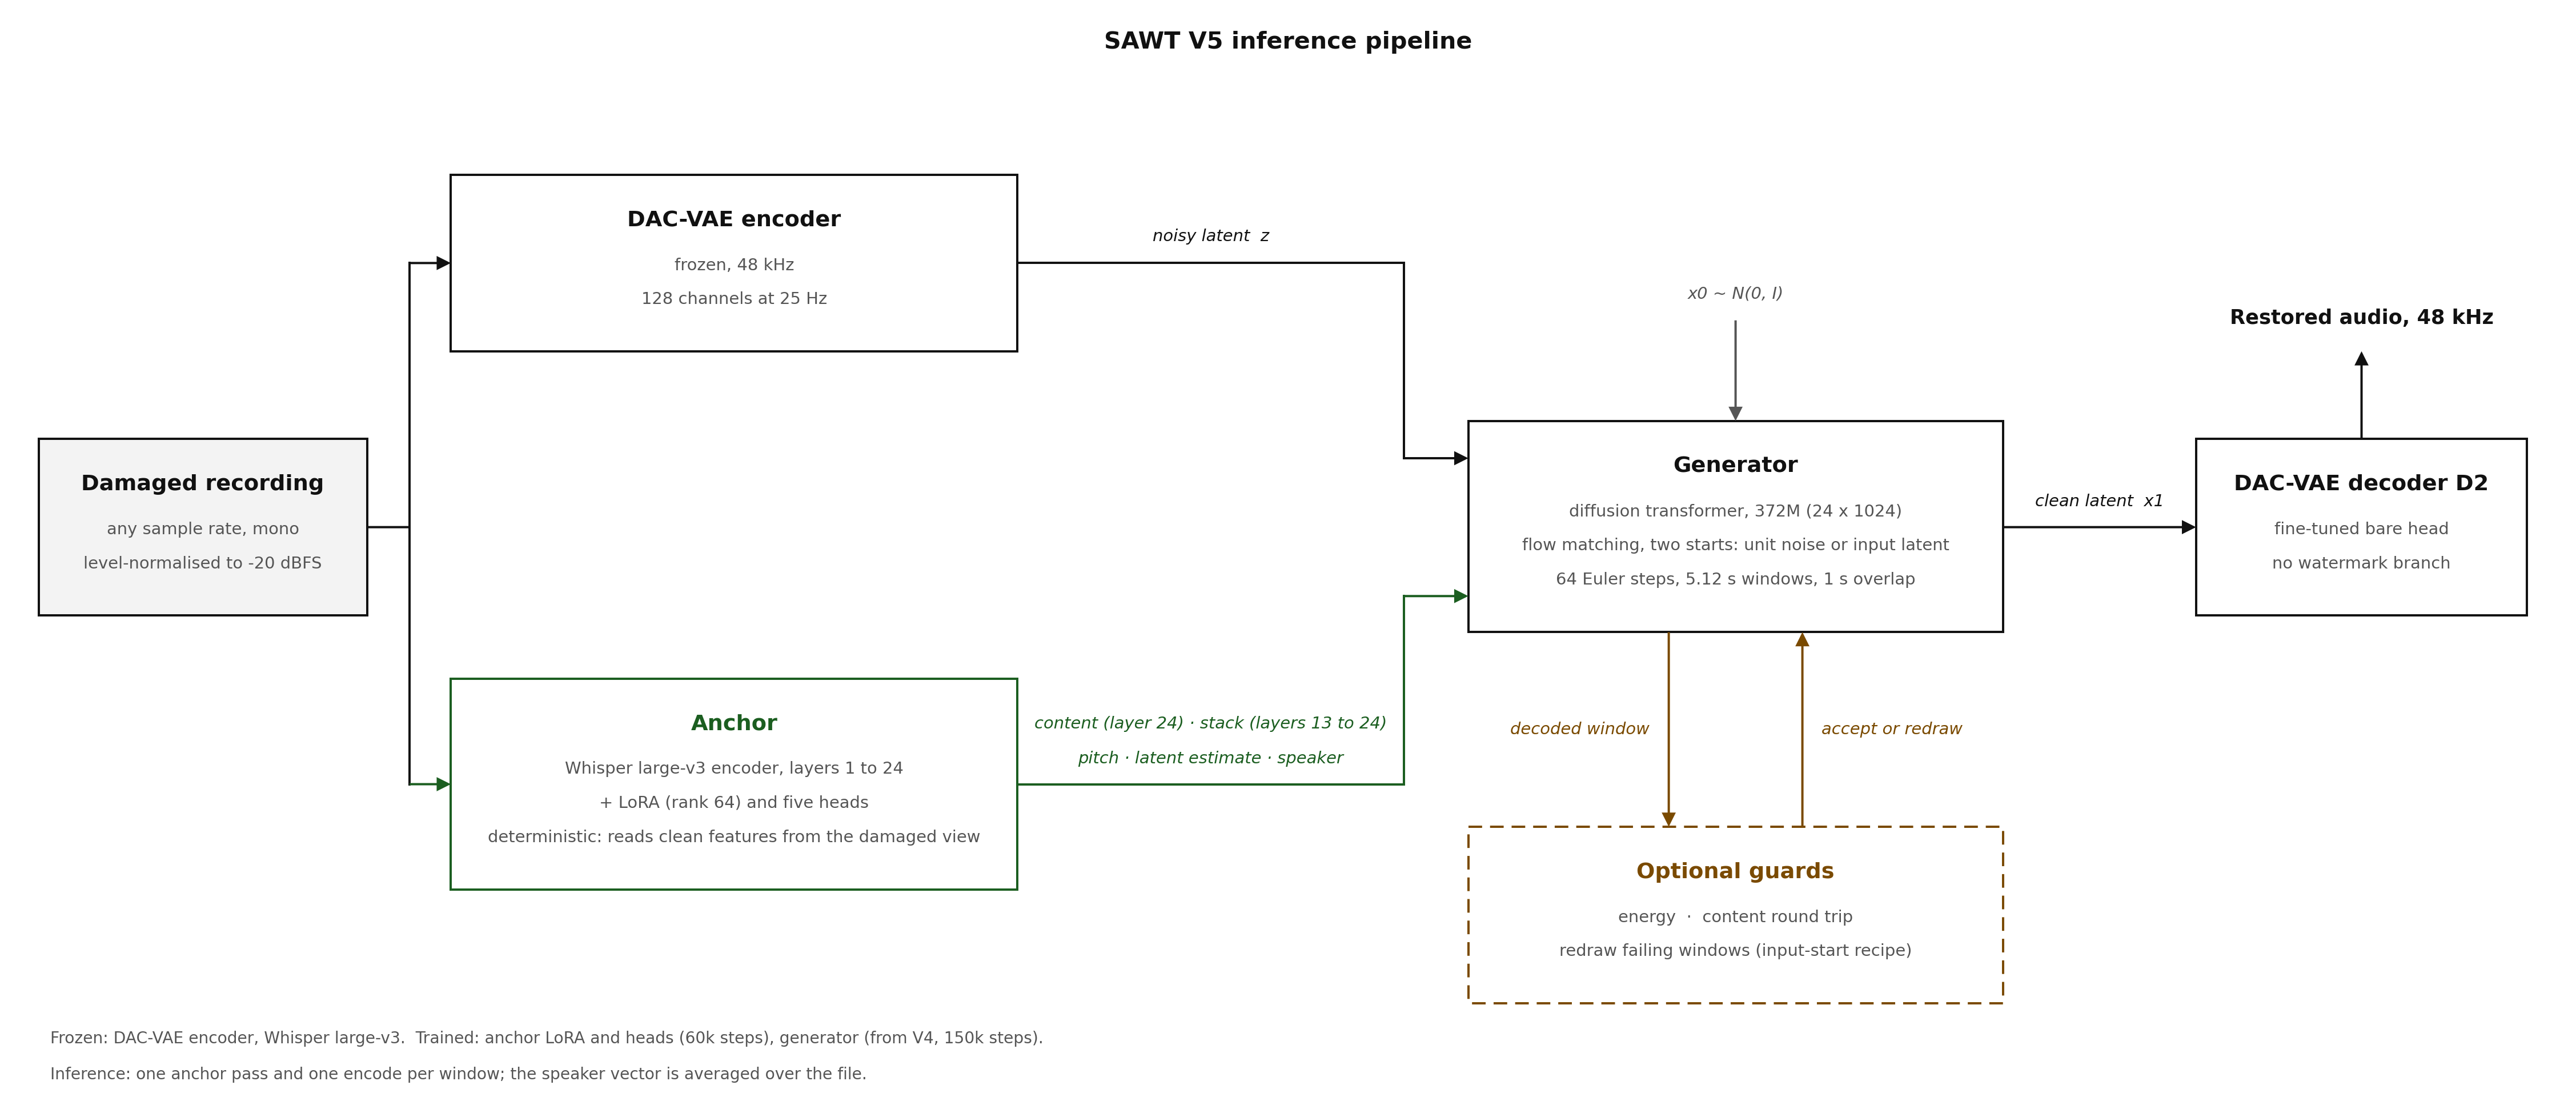
SAWT V5 inference pipeline: a DAC-VAE encoder and a Whisper large-v3 anchor feed a 372M diffusion transformer, decoded by the DAC-VAE decoder D2 to 48 kHz audio, with optional guards.
Open the image for full size.