Listen
Ten 10-second excerpts of real archive recordings from a 120-clip validation set that was not used in training. Every version of a clip is matched in loudness to the SAWT V6 Pro take. Start another version while one is playing and it picks up at the same moment, for a direct A/B. Headphones recommended.
Surah 59 (Al-Hashr), low-quality archive input
lowDistillMOS 3.75 to 3.87 (SAWT V5 Pro 3.70) · pauses -28 to -40 dBFS.
Surah 88 (Al-Ghashiyah), low-quality archive input
lowDistillMOS 2.55 to 3.79 (SAWT V5 Pro 3.33) · pauses -28 to -39 dBFS.
Surah 82 (Al-Infitar), mid-quality archive input
midDistillMOS 2.52 to 3.94 (SAWT V5 Pro 3.03) · pauses -29 to -59 dBFS.
Surah 87 (Al-A'la), mid-quality archive input
midDistillMOS 2.76 to 4.02 (SAWT V5 Pro 3.04) · pauses -29 to -42 dBFS.
Surah 20 (Ta-Ha), high-quality archive input
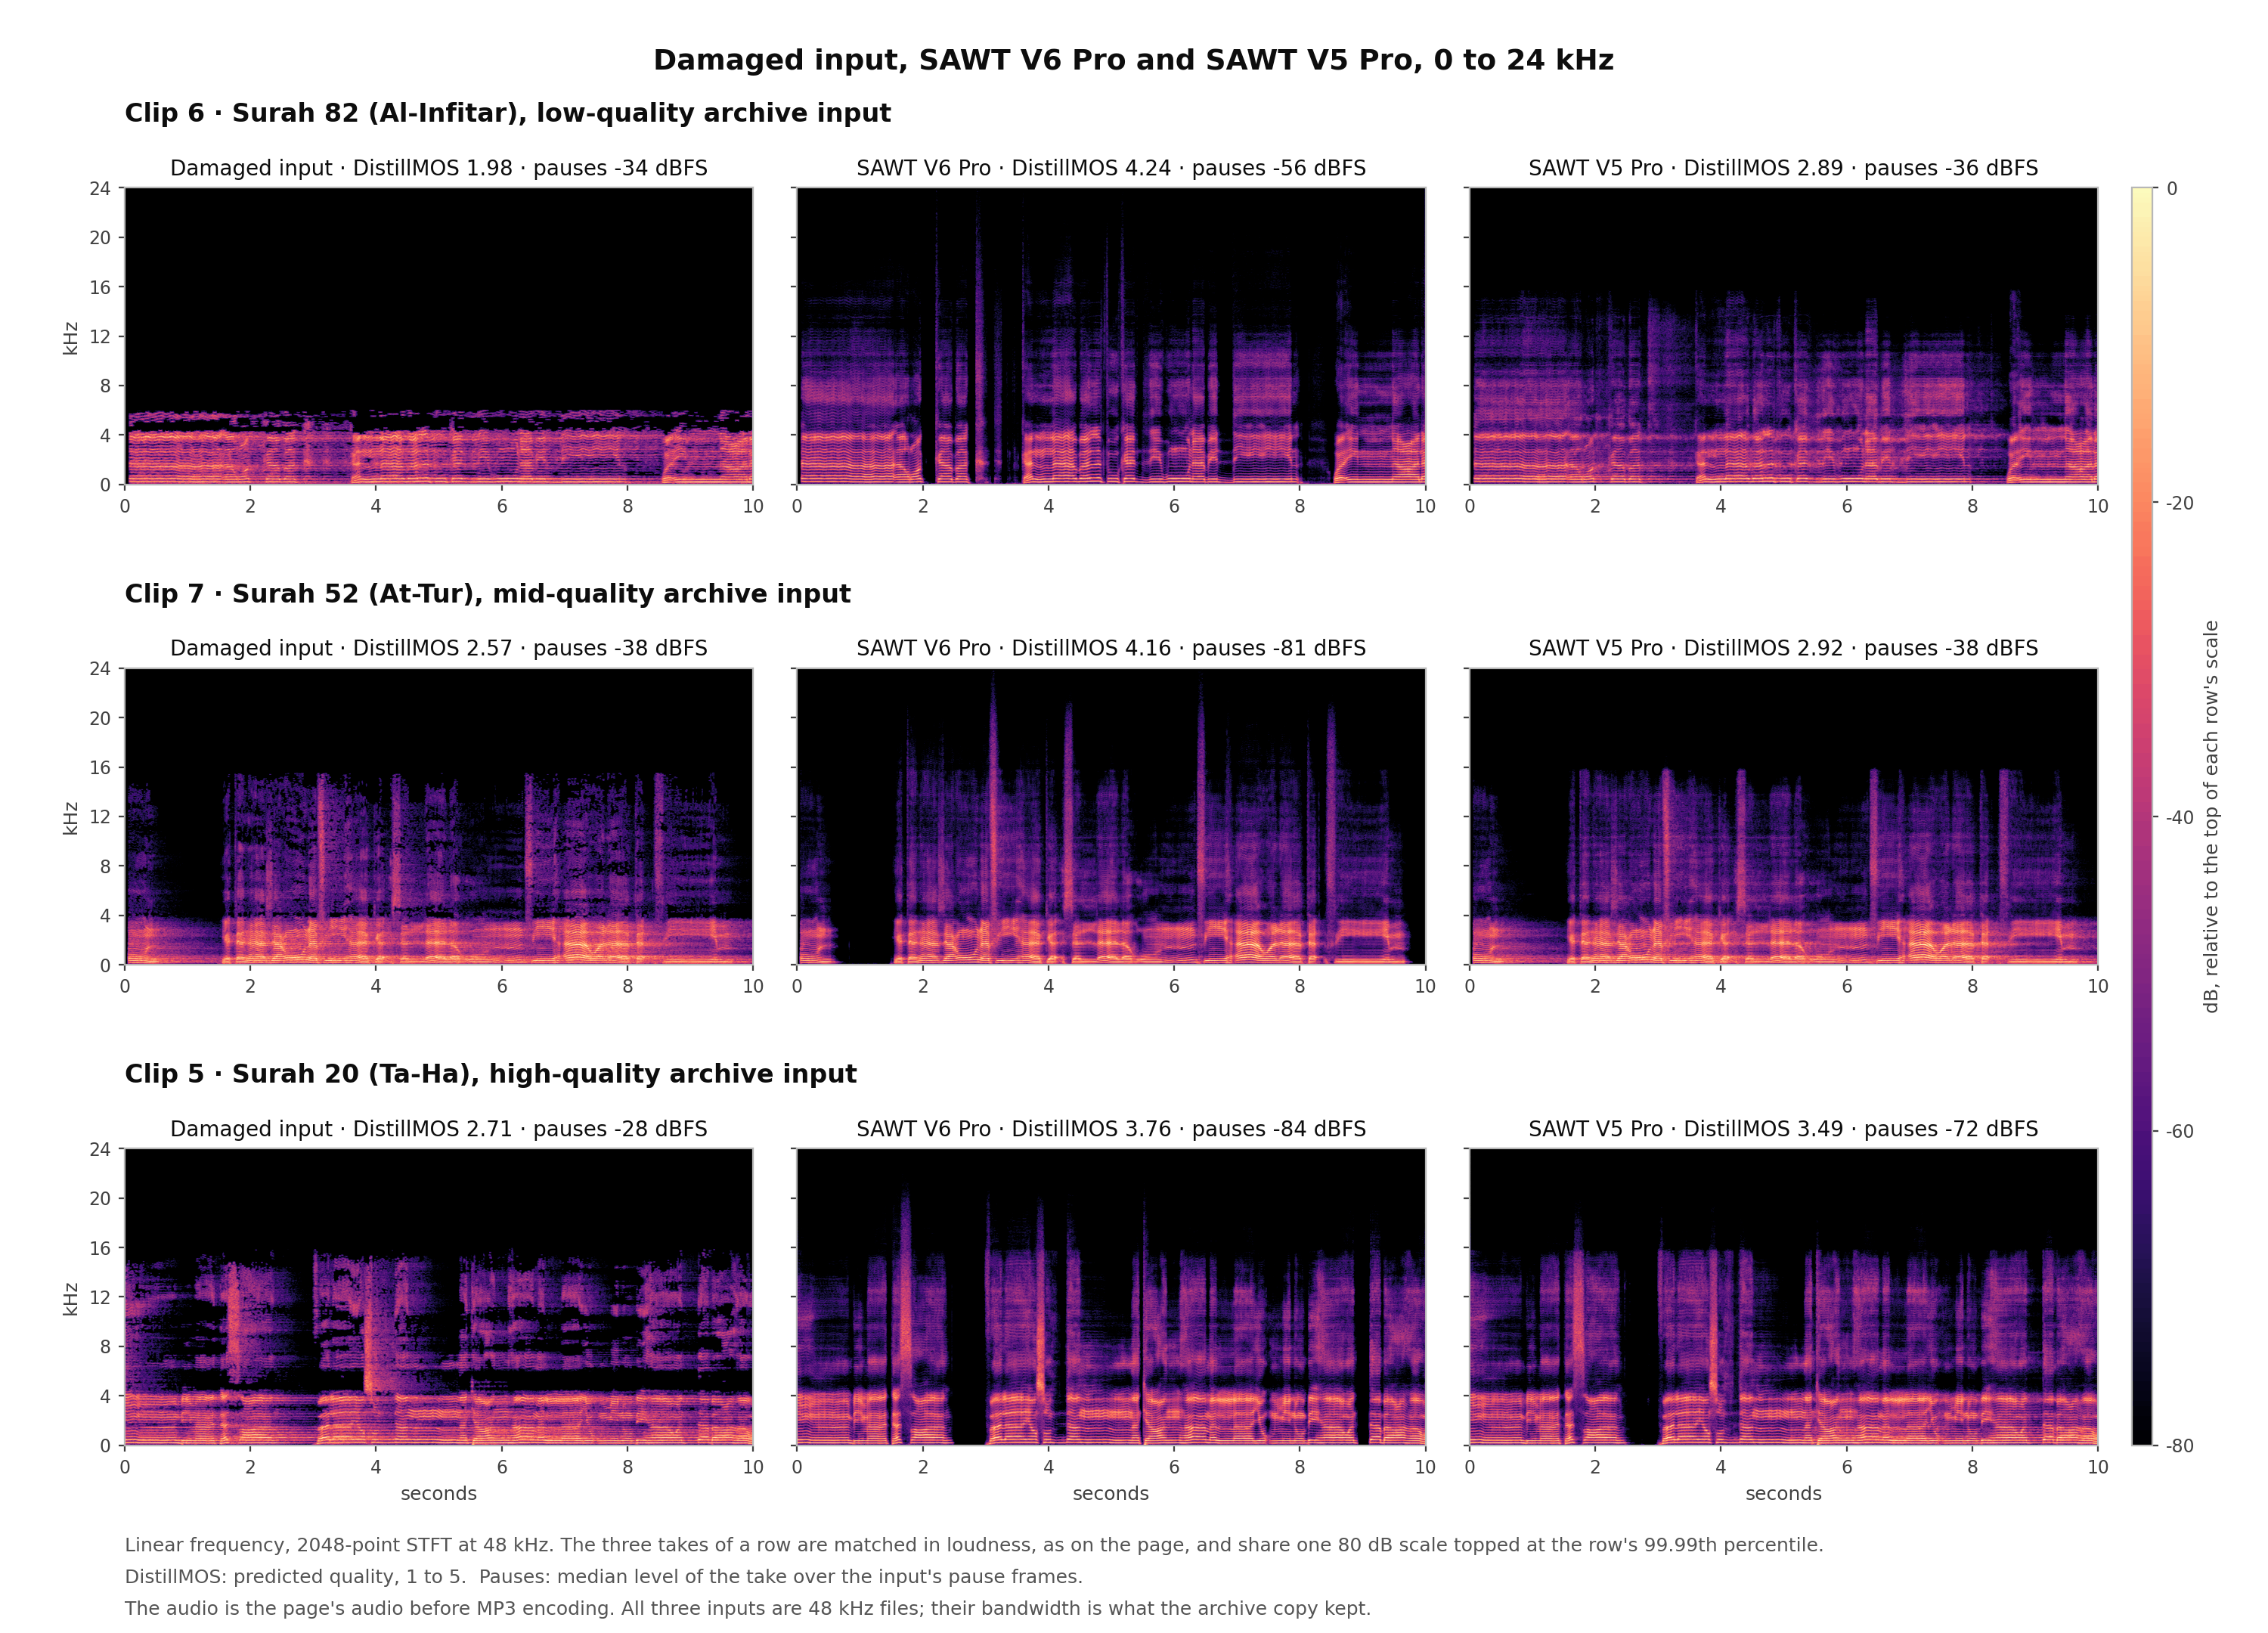
highDistillMOS 2.71 to 3.76 (SAWT V5 Pro 3.49) · pauses -28 to -84 dBFS.
Surah 82 (Al-Infitar), low-quality archive input
lowDistillMOS 1.98 to 4.24 (SAWT V5 Pro 2.89) · pauses -34 to -56 dBFS.
Surah 52 (At-Tur), mid-quality archive input
midDistillMOS 2.57 to 4.16 (SAWT V5 Pro 2.92) · pauses -38 to -81 dBFS.
Surah 62 (Al-Jumu'ah), mid-quality archive input
midDistillMOS 2.00 to 3.98 (SAWT V5 Pro 3.64) · pauses -21 to -69 dBFS.
Surah 96 (Al-Alaq), low-quality archive input
lowDistillMOS 1.74 to 3.47 (SAWT V5 Pro 3.13) · pauses -25 to -64 dBFS.
Surah 64 (At-Taghabun), low-quality archive input
lowDistillMOS 2.76 to 4.31 (SAWT V5 Pro 3.43) · pauses -34 to -55 dBFS.
Against open restorers
The same 120 validation clips through five open restoration models, scored the same way.
DistillMOS
predicted quality, 1 to 5; higher is better
Pause floor, dBFS
level in the input's pauses; lower is quieter
Pitch fidelity
share of voiced frames more than 50 cents off the input's pitch; lower is better
Reading the numbers
SAWT V6 Pro has the highest predicted quality of the six. Resemble Enhance has quieter pauses, but a lower quality score. Sidon, the strongest open model here, resynthesises the voice from speech-model features, and the melody is reinvented: about one voiced frame in five lands more than 50 cents off the input's pitch, against about one in nine for SAWT V6 Pro, and in recitation the melody is part of the reading. Not every number goes SAWT's way: SGMSE+ tracks the input's pitch a little more closely, though its pauses are far noisier and its quality score lower.
Pro and Flash
Two sizes of the same restoration. Flash is a student distilled from Pro: a third of the size, four sampling steps instead of sixteen, slightly less clean in the pauses.
SAWT V6 Pro
The flagship. Best quality and the cleanest pauses.
- Generator
- 351M diffusion transformer, 24 layers, width 1024
- Anchor
- omniASR CTC 1B (wav2vec2, 1,600+ languages)
- Sampling
- 16 Euler steps, anchor guidance 1.5
- Speed
- 16x real time on long recordings; about 8x on 10 s clips
SAWT V6 Flash
Distilled from SAWT V6 Pro for large archives and smaller GPUs.
- Generator
- 105M student, 12 layers, width 768
- Anchor
- omniASR CTC 300M
- Sampling
- 4 Euler steps
- Speed
- 74x real time on long recordings, 29x on 10 s clips
| Input | V5 Pro | V6 Pro | V6 Flash | |
|---|---|---|---|---|
| DistillMOS 1 to 5 | 2.78 | 3.47 | 3.89 | 3.68 |
| Pause floor, dBFS lower is quieter | -36 | -53 | -79 | -70 |
SAWT models on the 120-clip validation set. Speeds are on one RTX 4090. Each file is processed in 56 s windows, so short clips run slower relative to their length than long recordings do.
Spectrograms
How it works
An anchor that listens
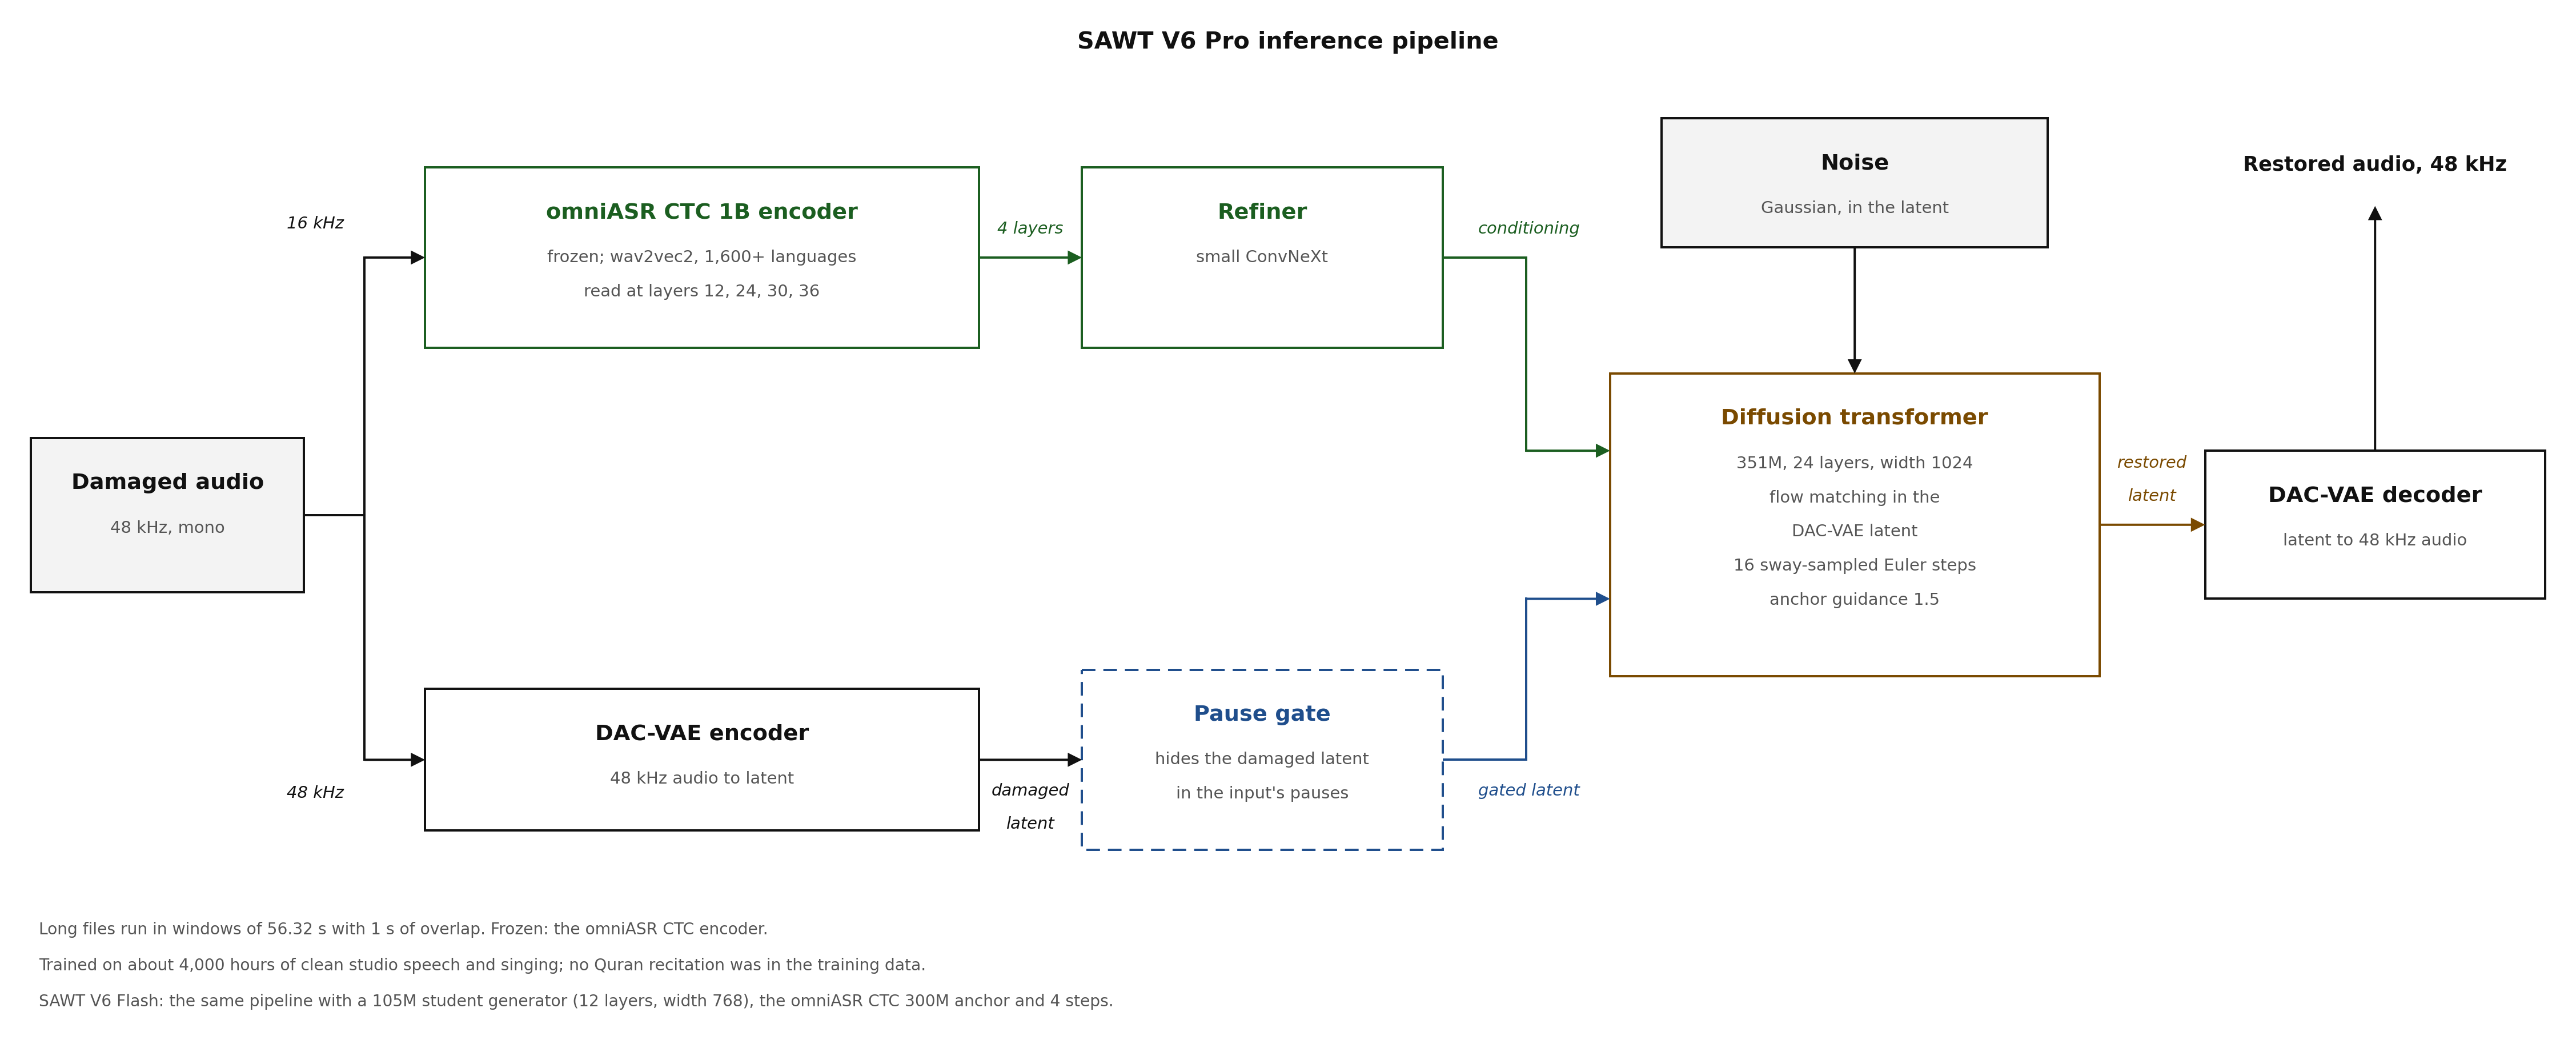
Meta's omniASR CTC 1B, a wav2vec2 recogniser trained on more than 1,600 languages, reads the damaged audio at 16 kHz. Its layers 12, 24, 30 and 36 go through a small ConvNeXt refiner and condition the generator. Anchor guidance, at a scale of 1.5, strengthens the anchor's pull at every step.
A generator in a 48 kHz latent
A 351M flow-matching diffusion transformer (24 layers, width 1024) starts from noise and takes 16 sway-sampled Euler steps in the DAC-VAE latent, which the DAC-VAE decoder turns into 48 kHz audio. Long files run in 56.32 s windows with 1 s of overlap.
A pause gate
The generator also sees the damaged recording's DAC-VAE latent. In the input's pauses the pause gate hides it, so the hiss and room tone in those stretches never reach the generator, and the silence between phrases stays silent.
Never trained on recitation
SAWT V6 Pro was trained on about 4,000 hours of clean studio speech and singing, with no Quran recitation in it. Recitation is what it is evaluated on and what it is released for; SAWT V6 Flash learned from SAWT V6 Pro.
Which model to use
SAWT V6 Pro
The best restoration of recitation we have measured: highest predicted quality and the cleanest pauses of the SAWT models.
SAWT V6 Flash
Four steps instead of sixteen. Pauses are a little less clean (-70 against -79 dBFS on the validation set) and predicted quality slightly lower (3.68 against 3.89).
SAWT V5 Pro
The previous SAWT. SAWT V5 Pro stays available; SAWT V6 Pro is the recommended model for recitation and speech alike.